LLM accelerator · NPU
openTARS
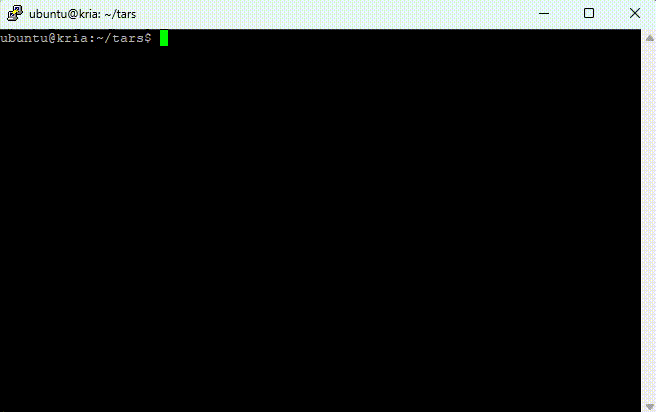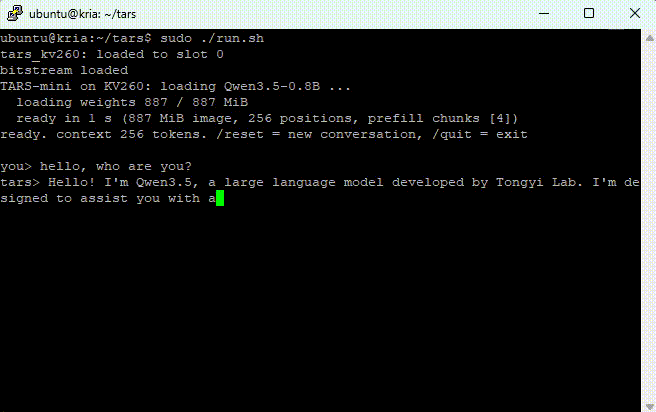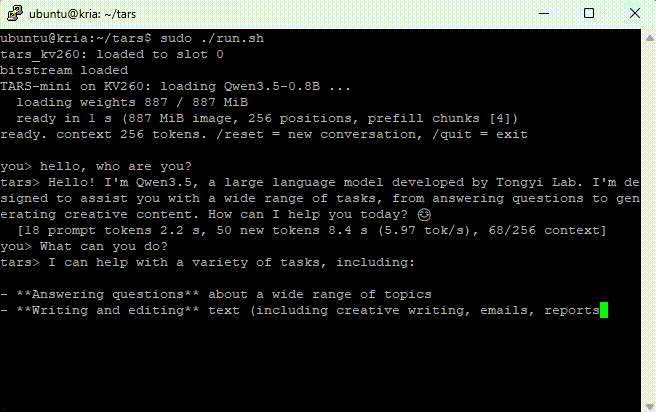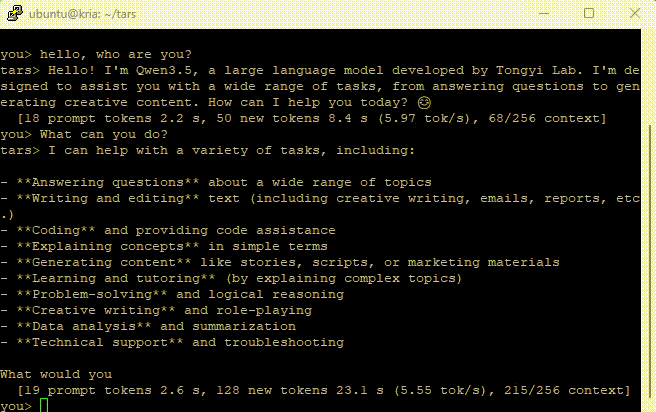
A single-core NPU that runs Qwen3.5-0.8B and Qwen3-0.6B on an off-the-shelf FPGA board, with every logit matching the golden model.
| Model | Layers | Decode | Model image |
|---|---|---|---|
| Qwen3.5-0.8B | 18 Gated DeltaNet + 6 gated attention | 0.13 s/tok | 887 MiB |
| Qwen3-0.6B | 28 full attention (GQA 16/8) | 0.07 s/tok | 662 MiB |
On the board
- Board
- AMD Kria KV260 (XCK26)
- Core clock
- 100 MHz
- LUT use
- 90%
- Weights
- INT8 W8A8
- Bitstream v1.0 → v3.3
- 2.6 → 0.13 s/token
How it is verified
- Executable contract and golden model in Python, checked against transformers before any RTL
- RTL vs golden, byte for byte: random queues, random stalls, five array shapes
- 748 regression tests and a 141-mutant check: every injected RTL bug must be caught
- Same core timed for ASIC: 1 GHz pre-layout on ASAP7
Honest numbers: MTP speculative decoding is implemented and bit-identical, but averages 0.97× on this hardware (break-even at 77% draft hits), so it ships off by default.
SystemVerilogVerilatorDRAMsim3VivadoYosys + ASAP7Python golden model
↳ Source: openTARS/README.md